Deploying Kubernetes Clusters on OpenStack: An Alternative to AWS EKS

Why VMs make more sense than bare metal for Kubernetes and distributed architecture, and where the cost and operational trade-offs come from.
Key Takeaways
- Deploying Kubernetes Clusters on OpenStack: An Alternative to AWS EKS.
- Why VMs make more sense than bare metal for Kubernetes and distributed architecture, and where the cost and operational trade-offs come from.
- Self-managed Kubernetes makes sense when you want to save some of your engineering budget.
Self-managed Kubernetes makes sense when you want to save some of your engineering budget. With OpenStack, you still get API-driven provisioning, private networking, and standard Terraform tooling without paying for a managed control plane.A three-node k3s cluster on cloud comes at about $346/month. A comparable EKS setup in us-east-1 costs around $914/month before adding load balancers, NAT gateways, storage, and egress. In this post, I’ll explain how we built this setup on an OpenStack provider, why VMs make more sense than bare metal for this architecture, and where the cost and operational trade-offs come from. Why VMS and Not Bare Metal Bare metal servers still win on raw price per GB of RAM. You pay for them in time. It can take hours or even days to get one up and running, and a dead disk has to be physically swapped. 3HCloud is somewhere in between. You don’t have to use a shared pool, as the VMs run on dedicated cores and are managed through a standard OpenStack API. The disks use external Fibre Channel SAN storage, so if a compute host dies, the VM restarts on another host with its data intact. That combination gives you hyperscaler-style flexibility, close-to-hardware pricing, and simpler failure recovery. Why We Want Kubernetes Clusters on Dedicated VMs We wanted a setup that keeps costs low without giving up the availability, simplicity, or security we need. That meant staying well below the price of a managed hyperscaler cluster without a multi-year commitment, while still being able to survive the loss of any single node, including its etcd member. We also wanted to keep the stack simple with k3s and plain Terraform, with no Kubernetes components exposed to the internet and application traffic routed only through Cloudflare. The Stack The stack consists of four main parts: Compute: 3HCloud cloud servers, provisioned with the standard terraform-provider-openstack/openstack provider. Kubernetes: k3s with embedded etcd on three server nodes. API endpoint: HAProxy and Keepalived holding a virtual IP on the private network. Ingress: Traefik (bundled with k3s) behind a Cloudflare Load Balancer, locked down with Authenticated Origin Pulls. Reading the Price Sheet 3HCloud prices its dedicated CPU flavors linearly. This makes choosing the right node size a simple compromise between blast radius, bin packing, and per-node overhead. All prices below are in USD per month. Family Flavor Prefix RAM per vCPU US $/month per vCPU US $ per GB RAM Sizes in the List Memory Optimized m- 6 GB 15 2.50 2 to 32 vCPU General Purpose g- 4 GB 14 3.50 2 to 32 vCPU CPU Optimized c- 2 GB 9 4.50 1 to 32 vCPU Shared Pool s- 1 to 2 GB 3 to 5 2.50 to 3.00 1 to 2 vCPU For a Kubernetes cluster, that means: RAM is the number to watch. Most clusters run out of memory long before CPU. Memory Optimized has the cheapest RAM in the catalog at $2.50/GB. CPU Optimized is the cheapest compute at $9 per vCPU. It’s a good fit for small control-plane nodes and CI runners. etcd should be kept off the shared pool. etcd is sensitive to latency, and a busy neighbour can show up as slow heartbeats and leader churn. Shared flavors are fine for labs and preview environments. Block storage and public IPv4 addresses are billed separately and are not in the price list we worked from. We’ve left them out here, and we’ll do so again in the EKS comparison later. Both sides are compute only. Four Ways to Lay Out the Cluster For this setup, we considered the following layouts: Layout Flavors Total vCPU / RAM US $/month Good for Lab 3 × s-4gb-2vcpu 6 / 12 GB 30 Dev and preview environments Small Production 3 × g-16gb-4vcpu 12 / 48 GB 168 A handful of services This Build 3 × g-32gb-8vcpu 24 / 96 GB 336 Production build Split Planes 3 × c-4gb-2vcpu + 3 × m-36gb-6vcpu 24 / 120 GB 324 Memory-heavy workloads The split layout is the interesting option. Three small CPU-optimized servers run the control plane and etcd. They are tainted, so nothing else is scheduled there. Three memory-optimized agents give your pods 108 GB, and in the US, the whole setup costs $12 less per month than the combined build. We went with the combined layout for this post because it has fewer moving parts. You can switch to the split layout later without redesigning the cluster. Architecture Every node runs k3s in server mode: an API server, a scheduler, a controller manager, an etcd member, and regular workloads. All cluster traffic stays on a 3HCloud private network. The public interfaces accept only HTTPS from Cloudflare and SSH from a bastion. Node Public IP Private IP Role k3s-one 203.0.113.10 10.0.0.10 server, etcd k3s-two 203.0.113.11 10.0.0.11 server, etcd k3s-three 203.0.113.12 10.0.0.12 server, etcd API VIP none 10.0.0.100 Kubernetes API through HAProxy There are three important differences from the bare-metal version: Public IPs are optional. Through the OpenStack API, a VM gets a public address only if you give it a port on the public network. We do, because Cloudflare needs an origin address. A private-only cluster behind 3HCloud's own Load Balancer is a valid alternative. Filtering happens before the VM. Security groups are enforced outside the guest, so we never have to deal with nftables on the nodes or fight k3s for its iptables chains. A hardware failure causes a reboot, not an outage. The disks are backed by the SAN storage, so if a host fails, the VM can restart on another host. An anti-affinity server group also keeps two etcd members from sharing a host in the first place. Public traffic enters only through Cloudflare on 443, admin access goes only through the bastion on 22, and all Kubernetes traffic stays on the private network.Infrastructure Provisioning Because 3HCloud exposes a standard OpenStack API, there’s no vendor-specific provider to learn. We use the community openstack provider and point it to an entry in clouds.yaml, so no credentials end up in the repo. terraform { required_providers { openstack = { source = "terraform-provider-openstack/openstack" version = "~> 3.0" } cloudflare = { source = "cloudflare/cloudflare" version = "~> 5.0" } } } provider "openstack" { cloud = "3hcloud" # entry in ~/.config/openstack/clouds.yaml } Servers are API objects, not orders. Terraform waits until the instance is ACTIVE, then returns, and a second plan is clean. There’s nothing to import and no attributes to comment out. Private Network We have one network and one subnet: resource "openstack_networking_network_v2" "k3s" { name = "k3s-private" admin_state_up = true } resource "openstack_networking_subnet_v2" "k3s" { name = "k3s-private" network_id = openstack_networking_network_v2.k3s.id cidr = "10.0.0.0/24" ip_version = 4 no_gateway = true # keep the default route on the public interface allocation_pool { start = "10.0.0.10" end = "10.0.0.99" # the VIP (10.0.0.100) stays outside the pool } } no_gateway stops DHCP on the private interface from installing a second default route. The allocation pool ends below the VIP, so Neutron can never hand that address to a new port. Security Groups The public group allows HTTPS from Cloudflare's ranges and SSH from the bastion. The private group, on the other hand, allows all traffic from inside the subnet, including VRRP (IP protocol 112) for Keepalived. resource "openstack_networking_secgroup_v2" "public" { name = "k3s-public" description = "HTTPS from Cloudflare, SSH from bastion" } resource "openstack_networking_secgroup_rule_v2" "https_cloudflare" { for_each = toset(var.cloudflare_ipv4_ranges) # from cloudflare.com/ips security_group_id = openstack_networking_secgroup_v2.public.id direction = "ingress" ethertype = "IPv4" protocol = "tcp" port_range_min = 443 port_range_max = 443 remote_ip_prefix = each.value } resource "openstack_networking_secgroup_rule_v2" "ssh_bastion" { security_group_id = openstack_networking_secgroup_v2.public.id direction = "ingress" ethertype = "IPv4" protocol = "tcp" port_range_min = 22 port_range_max = 22 remote_ip_prefix = var.bastion_cidr } resource "openstack_networking_secgroup_v2" "private" { name = "k3s-private" } resource "openstack_networking_secgroup_rule_v2" "private_all" { security_group_id = openstack_networking_secgroup_v2.private.id direction = "ingress" ethertype = "IPv4" remote_ip_prefix = "10.0.0.0/24" # no protocol = all, VRRP included } Ports, and the Keepalived “Gotcha” We create ports explicitly instead of letting Nova do it. That gives us fixed private IPs and lets us attach a different security group to each interface. locals { nodes = { "k3s-one" = "10.0.0.10" "k3s-two" = "10.0.0.11" "k3s-three" = "10.0.0.12" } api_vip = "10.0.0.100" } data "openstack_networking_network_v2" "public" { name = var.public_network_name # openstack network list --external } resource "openstack_networking_port_v2" "public" { for_each = local.nodes name = "${each.key}-public" network_id = data.openstack_networking_network_v2.public.id security_group_ids = [openstack_networking_secgroup_v2.public.id] } resource "openstack_networking_port_v2" "private" { for_each = local.nodes name = "${each.key}-private" network_id = openstack_networking_network_v2.k3s.id security_group_ids = [openstack_networking_secgroup_v2.private.id] fixed_ip { subnet_id = openstack_networking_subnet_v2.k3s.id ip_address = each.value } # Port security drops traffic from addresses not assigned to the port. # Without this pair, the VIP moves on failover but nobody can reach it. allowed_address_pairs { ip_address = local.api_vip } } If there’s one thing to remember from this section, it should be allowed_address_pairs. On bare metal, Keepalived just works on a flat L2 segment. On OpenStack, anti-spoofing filters on the port will silently drop packets sourced from the VIP until you’ve declared it. Servers Here’s how we handle servers: resource "openstack_compute_keypair_v2" "ops" { name = "ops" public_key = file("${path.module}/ops.pub") } resource "openstack_compute_servergroup_v2" "k3s" { name = "k3s-servers" policies = ["anti-affinity"] # one etcd member per hypervisor } data "openstack_images_image_v2" "ubuntu" { name_regex = "^Ubuntu 24\\.04" most_recent = true } resource "openstack_compute_instance_v2" "k3s" { for_each = local.nodes name = each.key flavor_name = "g-32gb-8vcpu" key_pair = openstack_compute_keypair_v2.ops.name block_device { uuid = data.openstack_images_image_v2.ubuntu.id source_type = "image" destination_type = "volume" volume_size = 100 boot_index = 0 delete_on_termination = true } network { port = openstack_networking_port_v2.public[each.key].id } network { port = openstack_networking_port_v2.private[each.key].id } scheduler_hints { group = openstack_compute_servergroup_v2.k3s.id } } To confirm the anti-affinity policy has done its job, compare the hostId of the three servers. It’s a hashed hypervisor ID that tenants can see. Three different values indicate three different hosts. for n in k3s-one k3s-two k3s-three; do openstack server show "$n" -f value -c hostId done Trade-Offs The main differences from EKS or GKE come down to who runs the cluster, what it costs, how it handles failures, and which Kubernetes you get. Management Overhead Your responsibilities are pretty much the same as on bare metal: the OS, the k3s lifecycle, etcd backups and restores, and every upgrade. The difference is that hardware, disk replacement, and provisioning lead time are handled for you. A broken node means terraform apply -replace plus a k3s join rather than opening a support ticket and waiting. Practice the etcd restore before you need it. k3s server --cluster-reset --cluster-reset-restore-path=<snapshot> is a five-minute drill on a staging cluster, but a very long night if you encounter it for the first time in production. Cost On-demand, the 3HCloud cluster costs a fraction of a comparable EKS cluster. Even with a three-year AWS Savings Plan, 3HCloud is still 24% cheaper. Setup Nodes Nodes $/month Control plane, LB $/month Total $/month 3HCloud Miami, Dallas or San Francisco 3 × g-32gb-8vcpu 336 10 (Cloudflare LB) 346 EKS us-east-1, 3-year EC2 Instance Savings Plan 3 × m6i.2xlarge 381 73 (EKS fee) 454 EKS us-east-1, on-demand 3 × m6i.2xlarge 841 73 (EKS fee) 914 We matched on vCPU count and RAM, which is how most capacity planning works. A vCPU isn’t the same unit on every cloud, so benchmark your own workload before trusting either column. Availability This is where hyperscalers still win. Every major AWS region has at least three availability zones. For 3HCloud, though, each location is one site. Within that site, the setup holds up well. SAN-backed disks turn a host failure into a VM restart, and the anti-affinity group means a single host failure takes out at most one etcd member. A site-level outage, however, still takes the entire cluster down. Don't try to solve that by stretching etcd across Dallas and Miami. Cross-region round trips slow down every write. Instead, you need to run a second, smaller cluster in another location and add its pool to the load balancer's default_pools. Cloudflare tries the pools in order, so failover happens through health checks without changing DNS. A small production layout in a second US site adds $168 a month. Kubernetes Distribution k3s is a certified Kubernetes distribution, but it’s not the same build that EKS runs. It bundles Traefik, ServiceLB, the local-path provisioner, and Flannel, while packaging the control plane as a single binary. For most workloads, that’s a feature. If you depend on a specific CNI, admission setup, or cloud integration, test them first. To Sum It Up Running Kubernetes on OpenStack gives you a middle ground between bare metal and a managed service like EKS. You keep API-driven provisioning, dedicated compute, private networking, and infrastructure automation with standard Terraform tooling, without paying the full cost of a managed hyperscaler stack. The downside is the operational responsibility. You’re still in charge of the Kubernetes lifecycle, etcd backups, upgrades, and recovery, and you also need to account for the fact that a single OpenStack location may not provide the same availability-zone model as AWS. If you want to build the cluster yourself, the next step is configuring the k3s nodes, HAProxy, Keepalived, storage, and ingress.
Read Complete Original Article
Published originally on HackerNoon
Related News
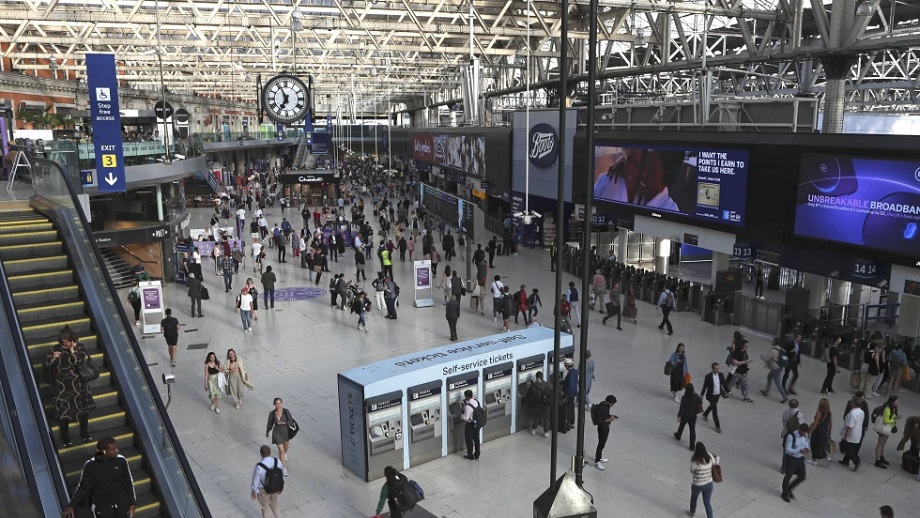
लन्डनमा मोबाइल कनेक्टिभिटी सुधार्ने प्रयास प्रभावकारी देखिएन
बेलायतको राजधानी लन्डनमा मोबाइल कनेक्टिभिटी सुधार गर्ने अभियानमा सहरका मेयर जुटेका छन्। तर, उनले हालै सार्वजनिक गरेको कार्ययोजना भने अपेक्षाअनुसार प्रभावकारी देखिएको छैन। लन्डनका मेयर सादिक खानले बिहीबार सहरमा मोबाइल नेटवर्कको सेवा कमजोर रहेका क्षेत्रबारे नयाँ प्रतिवेदन, स्थानीय प्रशासनिक क्षेत्रलाई कनेक्टिभिटी सुधार गर्न सहयोग गर्ने कार्यहरूको सूची र नेटवर्कको कार्यसम्पादन देखाउने अन्तरक्रियात्मक नक्सासम्बन्धी विवरण सार्वजनिक गरे। यस घोषणामा अपेक्षाअनुसार प्रचार धेरै गरिएको ...
एन्थ्रोपिकले गर्यो क्यानडामा पहिलो डाटा सेन्टरका लागि सम्झौता
एआई कम्पनी एन्थ्रोपिकले क्यानडाको नोभा स्कोटियास्थित पोइन्ट टपरमा डेटा सेन्टर सञ्चालनका लागि एभरविन्डसँग लिज सम्झौता गरेको छ। यो कम्पनीको क्यानडामा डाटा सेन्टरसम्बन्धी पहिलो सम्झौता हो। कम्पनीका एक अधिकारीले शुक्रबार दिएको जानकारीअनुसार एन्थ्रोपिकले आफ्नो एआई सहायक क्लोड सञ्चालनका लागि आवश्यक डाटा सेन्टर क्षमता उपयोग गर्न एभरविन्डसँग सम्झौता गरेको हो। यसैबीच, एभरविन्डले नोभा स्कोटियामा डेटा सेन्टर क्याम्पस र वायु ऊर्जा परियोजनामा १० अर्ब क्यानेडियन ...
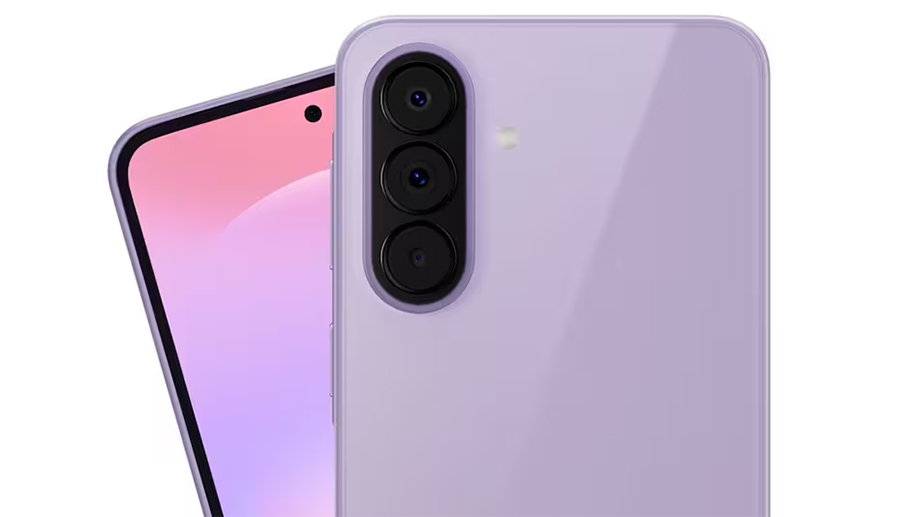
सामसङ ग्यालेक्सी ए३८ फाइभजीमा ट्रिपल रियर क्यामरा सेटअप हुनसक्ने
दक्षिण कोरियाली स्मार्टफोन निर्माता सामसङले आगामी केही महिनाभित्र ‘सामसङ ग्यालेक्सी ए३८ फाइभजी’ (Samsung Galaxy A38 5G) सार्वजनिक गर्न सक्ने रिपोर्ट गरिएको छ। यस स्मार्टफोनमा ‘ट्रिपल रियर क्यामरा’ सेटअप हुने अपेक्षा गरिएको छ, जसमा मुख्य क्यामरा ५० मेगापिक्सेलको हुनेछ। यो ‘सामसङ ग्यालेक्सी ए३७ फाइभजी’ को नयाँ संस्करण हुन सक्छ, जुन यस वर्षको मार्च महिनामा भारतमा सार्वजनिक गरिएको थियो। एक मिडिया रिपोर्टका अनुसार, सामसङ ...
I abandoned Incognito mode after learning how browser fingerprinting uses my hardware to track me - Android Police
I abandoned Incognito mode after learning how browser fingerprinting uses my hardware to track me Android Police
All Information In One Place
Real-time headlines from trusted sources. Get the app now — stay updated, inspired, and ahead with breaking news!