How Multi-Layer Caching Complicates Data Consistency in Production

I learned why caching across Nginx, Next.js, and Symfony creates freshness challenges, especially when eight Node.js processes maintain separate caches.
Key Takeaways
- How Multi-Layer Caching Complicates Data Consistency in Production.
- I learned why caching across Nginx, Next.js, and Symfony creates freshness challenges, especially when eight Node.js processes maintain separate caches.
- For a long time, I thought of caching as a performance feature.
For a long time, I thought of caching as a performance feature. You put a cache in front of something slow, and the thing gets faster. That mental model holds until the system grows enough independent caching layers that “how fast is it?” stops being the most interesting question. A harder question appears instead: when the underlying data changes, which layers may still contain an older version of it? I work on KOBOR, a production e-commerce platform built around Nginx, Next.js, a Symfony API, and MySQL. Over time, caching appeared at several layers, each for a legitimate reason. Static assets got long-lived immutable caching. Images got their own policy. Public HTML got a short shared cache. The Next.js application got an in-memory cache for frequently reused data. The PHP backend has its own FastCGI caching layer. None of these mechanisms is unusual on its own. Together, however, they changed the way I think about caching. It stopped being a single performance feature and became a question of freshness, ownership, and consistency. The Architecture Behind a Request A simplified view of a page request looks like this: The important detail is that several layers between the browser and the database can hold cached state independently. That is where the simple model starts to break down. Not Everything Should Have the Same TTL The first thing that breaks when you think of caching as one mechanism is the idea of a universal TTL. Different kinds of content have very different lifetimes. Static Next.js assets under /_next/static/ are fingerprinted. Their URLs change when the content changes, so they can be cached aggressively. In our Nginx configuration, these assets have a 365-day cache lifetime and are returned with: Cache-Control: public, max-age=31536000, immutable Optimized images under /_next/image follow a different policy. Nginx caches them for seven days, with stale-while-revalidate allowing an older response to be served while a newer one is prepared: Cache-Control: public, max-age=604800, stale-while-revalidate=86400 Public HTML is different again. For cacheable frontend pages, the Nginx cache lifetime is 15 minutes: Cache-Control: public, max-age=900, stale-while-revalidate=60 At the application level, the TTL depends on the data. For example, the root category list is cached for 10 minutes, while several pieces of homepage content are cached for 30 minutes and the new-products block for five minutes. These values are not a universal formula for e-commerce caching. They are examples from our current production configuration. The important point is that static assets, images, rendered HTML, and application data do not have the same freshness requirements. Public Pages and Private State A shared page cache is useful only when different users are allowed to receive the same cached representation. That makes the boundary between public content and user-specific state important. In our Nginx configuration, several routes are explicitly excluded from the shared frontend cache, including: /api/front /order /order-successful /order-error /profile /profile-order /favorites /compare /commercial-offer /restore-password /admin The cache policy also depends on the HTTP method. Only GET and HEAD requests are eligible for the shared frontend cache. When a request falls outside those conditions, Nginx bypasses the shared cache and returns a private no-cache policy: Cache-Control: no-store, no-cache, must-revalidate, private This is deliberately conservative. Checkout, profile pages, favorites, password recovery, administration, and other stateful routes should not accidentally inherit the caching policy used for public catalog pages. The frontend API follows the same separation. Requests under /api/front/ have proxy caching disabled explicitly. This distinction became important as the caching architecture grew: “the frontend is cached” is not a useful description anymore. Some representations are intentionally shared, while others are intentionally kept outside the shared cache. Eight Next.js Processes Changed the Meaning of “Memory Cache” This is where the architecture becomes more interesting. The frontend does not run as a single Node.js process. PM2 starts eight independent Next.js processes in fork mode, listening on ports 3001 through 3008. Nginx distributes frontend requests across that upstream cluster. At the same time, the application has a small caching helper called remember(). Its storage is intentionally simple: two JavaScript Maps. const memoryCache = new Map<string, CacheEntry<any>>(); const pendingRequests = new Map<string, Promise<any>>(); The first Map stores cached values and their expiration times. The second stores requests that are already in progress. That implementation has an important consequence: the cache lives inside the memory of a Node.js process. With eight independent processes, there is not one application memory cache. There can be eight. That does not automatically make the design wrong. A process-local cache has useful properties: it is simple, fast to access, requires no additional service, and introduces no network request for a cache lookup. But its scope has to be understood correctly. Each process can populate the same key at a different moment. Each process can therefore have a different expiration time. Restarting one process removes its cache without affecting the others. And clearing a key in one process does not automatically clear that key in the other seven. This distinction also matters for requests that arrive at the same time. Request Coalescing at Two Layers The remember() helper does more than store values with a TTL. It also keeps track of requests that are already in progress. The core logic is: const pending = pendingRequests.get(key); if (pending) { return pending; } const request = callback() .then((value) => { memoryCache.set(key, { value, expires: Date.now() + ttl, }); pendingRequests.delete(key); return value; }) .catch((err) => { pendingRequests.delete(key); throw err; }); pendingRequests.set(key, request); return request; If several requests for the same missing or expired key reach the same Node.js process at roughly the same time, the first request starts the callback and stores its Promise. The others reuse that Promise instead of executing the callback again. This is request coalescing at the application level. But the scope matters again: pendingRequests is also a process-local Map. It prevents duplicate work inside one Node.js process, not across all eight processes. Nginx has a related mechanism at a different layer: proxy_cache_lock on; proxy_cache_lock_timeout 10s; Here the unit of work is different. Nginx coordinates generation of a cached HTTP response, while pendingRequests coordinates execution of an application callback for a particular cache key inside one Node.js process. They address a similar class of problem — avoiding unnecessary duplicate work — but at different layers of the stack. This is one reason I no longer find the phrase “we have caching” particularly useful. The more useful questions are: what is being cached, where is it cached, and what is the scope of that cache? Optimize the MISS, Not Just the HIT A cache makes the HIT path easy to optimize because the expensive work has already been done. But production systems still have to behave reasonably when the cache is empty. The home page uses getServerSideProps and depends on several independent data sources. At one point in the implementation, those independent requests were being awaited sequentially. The current implementation starts them before waiting for the results: const pagePromise = ...; const brandsPromise = ...; const categoriesListPromise = ...; const promoSliderPromise = ...; const jobsListPromise = ...; const newProductsPromise = ...; const popularProductsSourcePromise = ...; const kitsListPromise = ...; This allows independent work to proceed concurrently instead of forcing one request to finish before the next begins. The important part for me is not a benchmark number — I do not want to invent one where I do not have a measurement to publish. The architectural point is that cache misses are normal events. They happen after expiration, after process restarts, on bypassed routes, and whenever a cache has not been populated yet. A cache should reduce expensive work, but it should not become an excuse to leave the uncached path unnecessarily serialized. The Hard Part Is Freshness Once several independent caching layers exist, the difficult question is no longer “how do we cache this?” It becomes: when the underlying data changes, which layers may still contain an older representation? In this architecture, freshness can be affected by several independent mechanisms: the browser cache, the Nginx cache for static assets and images, the shared HTML cache, Next.js rendering behavior, process-local application memory, the FastCGI cache, and finally the current state of the API and database. Each layer follows its own rules. A layer does not automatically know that another layer is holding an older representation of the same underlying data. This also means that TTLs should not simply be added together. A 15-minute Nginx TTL and a 30-minute application TTL do not give us a simple 45-minute staleness window. Their interaction depends on when each entry was populated, which Node.js process handles regeneration, what that process already has in memory, and when the underlying data changed. Consider a simplified example. T0 Process A loads value X into its local memory cache. T5 Nginx generates an HTML response containing X and stores that response in its page cache. T10 The underlying source changes from X to Y. T20 A request can still receive the cached HTML containing X. Later The Nginx entry expires and the page is regenerated. The process selected for regeneration may itself have cached dependencies with their own expiration times. This is an illustrative timeline, not a production incident. Its purpose is to show why the age of the final HTML cannot be inferred from one TTL in isolation. No individual cache has to be malfunctioning for this to happen. Every layer can behave exactly as configured while the complete request path still contains several different notions of “fresh.” That changed the way I look at cache invalidation. The useful question is not only “when does this key expire?” It is also “what else was generated from this value, and which layer owns the responsibility for making it fresh again?” What I Would Design Differently Today Looking at this architecture today, I would not replace every cache with one centralized system. Different layers exist for good reasons. What I would change is how explicitly their responsibilities are defined. Define Cache Ownership For important data, I want one clear answer to the question: which layer owns freshness? A browser cache, Nginx page cache, Next.js memory cache, and backend cache should not independently make freshness decisions for the same piece of data without an understood hierarchy. The goal is not necessarily fewer caches. It is fewer ambiguous responsibilities. Use Explicit Invalidation Where It Matters TTL-based expiration is simple and useful, but it is imprecise. For selected updates, explicit invalidation can be more appropriate than waiting for several timers to expire. The difficult part is dependency tracking. A single change may affect a product page, a category page, a homepage block, or another derived representation. Invalidating one cache key is easy. Knowing every representation affected by a change is the harder problem. Use a Shared Cache Selectively The eight process-local Maps do not automatically need to be replaced. For data where small differences between processes are acceptable, local memory remains attractive because it is simple and requires no additional network service. For data that requires stronger consistency across all Next.js processes, a shared cache such as Redis would be an option. I would make that decision per type of data rather than treating “move everything to Redis” as an architectural goal. Make Cache Behavior Observable The Nginx layer already exposes X-Cache-Status, which helps distinguish states such as HIT and MISS. I would extend that idea deeper into the application. Useful signals would include application-cache hit rates, regeneration duration, the number of backend requests triggered by misses, the age of cached values, and explicit invalidation events. Without observability, multi-layer cache behavior is too easy to reason about from assumptions rather than evidence. Lessons From Maintaining the System Working with this architecture changed a few assumptions I had about caching. A cache is not only a performance optimization. It is also a decision about how long an older representation is allowed to exist. A local memory cache is not a shared cache. In a multi-process deployment, a JavaScript Map belongs to one process, even when the application looks like one service from the outside. Request coalescing also has scope. Nginx can coordinate generation of an HTTP response, while pendingRequests can coordinate application work inside one Node.js process. Similar idea, different boundary. The MISS path deserves attention too. A fast cached response does not make an unnecessarily serialized regeneration path disappear. And TTLs do not compose into one simple freshness number. Once several layers cache related representations independently, timing and ownership matter more than arithmetic. Conclusion Caching in a production e-commerce system is not one switch and not one TTL. In our case, static assets, optimized images, public HTML, application data, and backend responses can all be subject to different caching rules. The Next.js frontend itself runs as eight independent processes, which means even “the application cache” is not necessarily one cache. None of those mechanisms is particularly exotic. The complexity comes from their interaction. The question I now find most useful is not “do we cache this?” It is: Where is this representation cached, who owns its freshness, and what happens when the underlying data changes? Once those questions have explicit answers, multi-layer caching becomes much easier to reason about.
Read Complete Original Article
Published originally on HackerNoon
Related News
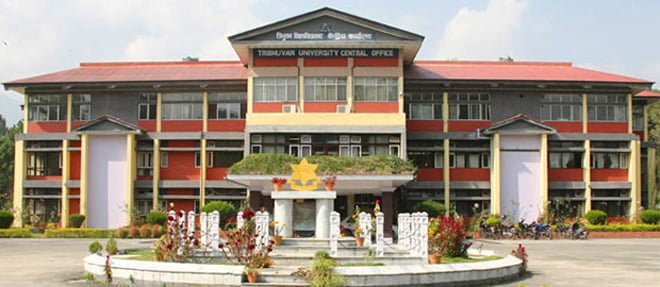
‘डिजिटल त्रिवि’देखि ‘रिसर्च युनिभर्सिटी’सम्मः के–के हुँदैछन् नयाँ काम?
त्रिभुवन विश्वविद्यालयले आफ्नो प्रशासनिक, शैक्षिक तथा प्राज्ञिक संरचनालाई समयानुकूल बनाउँदै डिजिटल सेवा विस्तार, अनुसन्धान प्रवर्द्धन, संस्थागत पुनःसंरचना र वित्तीय सुधारका नयाँ योजना अघि सारेको छ। त्रिविका सहकुलपति एवं शिक्षा तथा खेलकुदमन्त्री सस्मित पोखरेलको अध्यक्षतामा बसेको विश्वविद्यालय सभामा चालु आर्थिक वर्षको नीति तथा कार्यक्रम प्रस्तुत गरिएको थियो। यी योजना कार्यान्वयन भएमा विश्वविद्यालयको प्रशासनिक, शैक्षिक र प्राज्ञिक स्वरूपमा ठूलो फेरबदल आउने अपेक्षा गरिएको ...

इन्टरनेट प्याकेज र शुल्कमा प्राधिकरणको निगरानी, १४ सेवा प्रदायक कारबाहीमा
काठमाडौं । नेपाल दूरसञ्चार प्राधिकरणले स्वीकृत मापदण्ड र निर्देशनविपरीत इन्टरनेट सेवा सञ्चालन गरेको भन्दै १४ वटा इन्टरनेट सेवा प्रदायक कम्पनीलाई जनही ५० हजार रुपैयाँ जरिवाना गरेको छ ।प्राधिकरणले मंगलबार जारी गरेको प्रेस विज्ञप्तिअनुसार अनुमतिपत्रका सर्त उल्लङ्घन गरेको निरीक्षण तथा जाँचबुझबाट पुष्टि भएपछि दूरसञ्चार ऐन, २०५३ को दफा ४७ (१) बमोजिम कारबाही गरिएको हो ।प्राधिकरणका प्रवक्ता मिनप्रसाद अर्यालका अनुसार स्वीकृत प्याकेजअनुसार ...
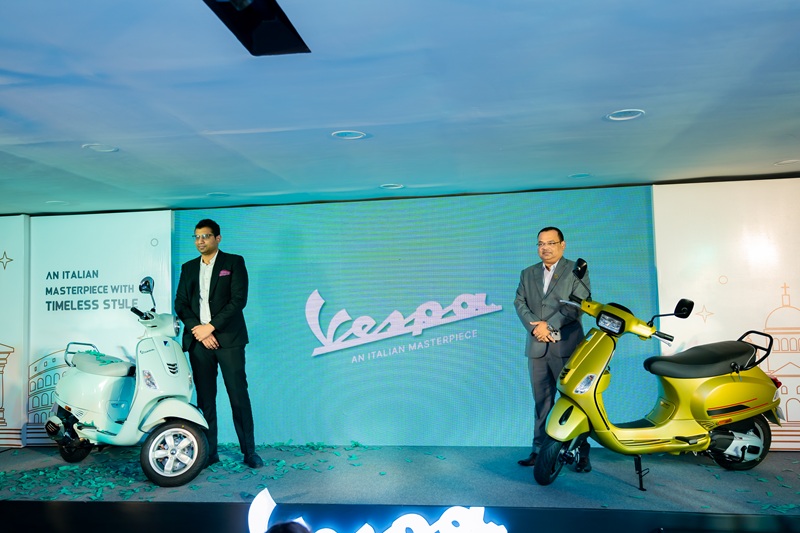
नेपालमा सार्वजनिक भयो भेस्पा १५० एफआई ओबीडी २ स्टेज बी: विशेषता तथा विवरण
२७ असोज, काठमाडौं। इटालियन स्कुटर ब्रान्ड भेस्पाले नेपाली बजारमा नयाँ १५० सिसी क्षमताको स्कुटर सार्वजनिक गरेको छ । नेपालका लागि भेस्पाको आधिकारिक वितरक डेल्टा अटोकर्प प्रालिले भेस्पा १५० एफआई ओबीडी २ स्टेज बी (Vespa 150 FI OBD 2 Stage B) सार्वजनिक गरेको हो । काठमाडौँको त्रिपुरेश्वरस्थित डेल्टा अटोकर्पको शोरुममा आयोजित विशेष कार्यक्रममार्फत नयाँ मोडल सार्वजनिक गरिएको […] The post नेपालमा सार्वजनिक ...
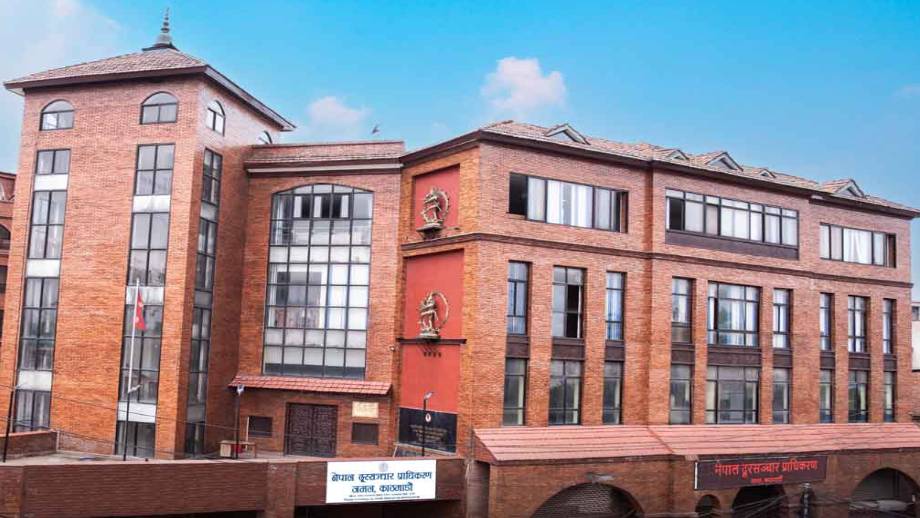
आफूखुशी शुल्क बढाउने १४ इन्टरनेट सेवा प्रदायकलाई प्राधिकरणले तिरायो जरिवाना, स्वीकृति नलिई लागू गरिएका प्याकेज र शुल्क तत्काल बन्द गर्न निर्देशन
नेपाल दूरसञ्चार प्राधिकरणले अनुमतिपत्रका शर्तविपरीत काम गरेको भन्दै १४ वटा इन्टरनेट सेवा प्रदायकलाई जनही ५० हजार रुपैयाँ जरिवाना गरेको छ। प्राधिकरणले आज एक विज्ञप्ति जारी गर्दै इन्टरनेट (इमेलसहित) सेवा सञ्चालन गर्न अनुमति पाएका सेवा प्रदायकले अनुमतिपत्रका सर्त तथा प्रचलित कानुनअनुसार सेवा सञ्चालन नगरेको निरीक्षण तथा जाँचबुझ प्रतिवेदनका आधारमा जरिवाना गर्ने निर्णय गरिएको जनाएको छ। दूरसञ्चार ऐन, २०५३ को दफा ४७(१) बमोजिम ती ...
All Information In One Place
Real-time headlines from trusted sources. Get the app now — stay updated, inspired, and ahead with breaking news!