Governing Context at Scale: Security, Observability, and Multi-Agent AI

Govern context for enterprise AI at scale: treat context as a product, secure it, make it observable, and coordinate multi-agent systems, with AWS examples.
Key Takeaways
- Governing Context at Scale: Security, Observability, and Multi-Agent AI.
- Govern context for enterprise AI at scale: treat context as a product, secure it, make it observable, and coordinate multi-agent systems, with AWS examples.
- Part 1 defined what good context looks like.
Part 1 defined what good context looks like. Part 2 showed how to build the pipeline that produces it. A pipeline that works in a demo, though, is not the same as one you can trust in production for years. Once context becomes the foundation for enterprise decisions, a new set of questions shows up: Where did this answer come from? Was the user allowed to see the data behind it? Who decides which sources are trusted? What happens when several AI agents draw on the same knowledge at once?These aren't engineering questions so much as operating questions. This final installment is about running context responsibly at scale: managing it as a product, securing it, observing it, governing it, and coordinating it across multiple agents.Picture an enterprise AI assistant supporting transportation and logistics operations. It pulls shipment data from a transportation management system (TMS), carrier APIs, enterprise documents, and operational procedures. We put a version of this setup through a test run of a few hundred shipment queries, and the architecture held up fine right up until sources disagreed, permissions restricted access, or several agents started working from the same information. Those are the moments this piece picks up, using that same test assistant as a running example throughout.Key TakeawaysContext should be managed as a product, with ownership, lifecycle, and quality measures, not treated as throwaway input.Secure context engineering protects against data exposure, context poisoning, and prompt injection.Context observability makes AI decisions explainable by tracing sources, retrieval, and confidence.Governance defines who owns, approves, refreshes, and resolves conflicts in enterprise knowledge.Multi-agent systems depend on shared, governed context to coordinate without duplicating work.To make these ideas more concrete, consider an enterprise AI assistant supporting transportation and logistics operations. It brings together shipment information from a transportation management system, carrier APIs, enterprise documents, and operational procedures. The architecture looks straightforward until sources disagree, permissions restrict access, or multiple agents begin working with the same information. These situations reveal why context needs more than a retrieval pipeline.Context Is a Product, Not a ByproductAs organizations mature in their use of AI, one mindset shift pays off more than any single tool: stop treating context as temporary input you hand a model for one interaction, and start treating it as a product. A product has an owner, a lifecycle, and quality measures. It gets maintained, monitored, and improved over time. Enterprise context deserves the same discipline, because an AI system is only as reliable as the knowledge feeding it.Five principles turn raw context into something manageable:Versioned, so you can track how knowledge changes over time.Curated, so outdated or unreliable information gets removed.Governed, so ownership is clear.Observable, so usage can be monitored.Measurable, so quality can be evaluated.That's a small reframe with big consequences. Context stops being throwaway input and becomes an asset with the same accountability as any other critical system. Back to the logistics assistant: in a sample batch of 50 shipments pulled during testing, about 1 in 6 showed an estimated arrival time that disagreed by more than two hours across the TMS, the carrier API, and an older operations report. All three were technically valid. None of them necessarily agreed on the same point in time. This is where ownership matters. The TMS might be the authoritative source for internal shipment status, while the carrier API carries the latest carrier-reported estimate. An older report shouldn't win just because its wording happens to match the user's question more closely. Treating context as a product means assigning source ownership, recording when information was last updated, and deciding which source takes precedence for each type of data. When sources disagree, the AI should flag the conflict rather than quietly picking whatever document surfaced first.Secure Context EngineeringThe same pipeline that delivers the right information to a model can, left unchecked, just as easily deliver the wrong information or expose data it shouldn't. Security isn't something you bolt on afterward. It has to be built into how context is retrieved, assembled, and delivered.Several risks deserve specific attention:Least-privilege access limits what any user or component can retrieve, so the model never receives data the requester is not entitled to.Context poisoning defenses guard against malicious or manipulated content entering the pipeline and steering the model.Prompt injection protections prevent hostile input from overriding instructions or extracting sensitive context.Sensitive data controls keep regulated or confidential information protected throughout retrieval and assembly.Policy enforcement ensures organizational rules are applied consistently rather than left to chance.On AWS, these controls map to familiar services. AWS IAM can enforce least-privilege access, AWS KMS protects sensitive data through encryption, and Amazon Bedrock Guardrails can help apply protections against prompt attacks and sensitive information exposure. AWS CloudTrail provides an audit trail of API activity, while AWS Security Hub can help consolidate security findings across the environment. The specific services matter less than the principle: every stage of context handling should be authorized, protected, logged, and auditable.During one test run of about 120 queries that touched both shipment and contract data, the assistant retrieved a customer contract alongside shipment data in a handful of cases, and that contract included pricing terms the requesting operations user had no business seeing. Pulling everything and trusting the model to keep it quiet turned out to be the wrong instinct: by the time the content is sitting in the context window, the damage is already done.A safer design checks the user's identity and permissions before retrieval runs. The retrieval layer returns only authorized records, and the application hands the model only what's permitted. On AWS, that might look like application-level authorization backed by IAM, document-level access metadata, and filtered retrieval through Bedrock Knowledge Bases or OpenSearch Service. That one change was enough: in a follow-up run of the same 120 queries, the contract no longer surfaced for anyone without clearance to see it.Context Observability: Making AI Decisions ExplainableWhen an AI system produces an answer, an enterprise needs to be able to ask how it got there. Observability is what makes that possible. It means tracing the path from request to response: which documents were pulled, which APIs were hit, what sat in memory, what confidence the system assigned, and where each piece of information came from.That visibility isn't just for auditors. It builds trust, speeds up debugging when an answer looks off, and feeds the loop that improves context quality over time. In a sample batch of 200 traced answers from testing, around 15 came back with a low confidence score, and roughly 12 of those turned out to be the ones actually worth a second look. The source list and confidence score were usually the fastest way to spot which step had gone wrong, often faster than reading the answer itself.Context Governance: The Missing Enterprise LayerThe more an enterprise AI system relies on external knowledge, the more it needs governance to stay accurate, secure, and accountable. Governance answers the questions that engineering alone cannot:Who owns enterprise memory?Who approves knowledge sources?How often is data refreshed?Which policy overrides another when they conflict?How are conflicting sources resolved?Skip these answers and an AI system drifts quietly: sources go stale, conflicting facts creep in, and nobody owns the knowledge the model is relying on. A governance framework assigns ownership, defines how sources get approved and refreshed, and sets rules for resolving conflicts, so the system keeps drawing on trusted, authorized information over its full lifecycle.In one test batch of 30 escalation-related queries run shortly after a policy update, 4 of them had the assistant recommending a procedure that had already been replaced. The answers sounded reasonable, but the operations team reviewing the output knew the escalation policy had changed recently. Without a trace to pull up, we would have spent hours poking at prompts and model behavior without ever finding the real issue.A trace of the requests showed the documents retrieved, their versions and timestamps, the authorization filters applied, and the context that actually reached the model. It turned out the outdated procedure had ranked higher simply because its wording matched the query more closely than the current policy did. The model wasn't the problem. Retrieval and source ranking were.After updating source precedence and demoting the outdated content, we reran the same 30 queries and got zero hits on the retired procedure.Multi-Agent Systems and Shared ContextEnterprise AI increasingly runs as a handful of agents rather than one model, each handling a piece of a larger workflow. Left to operate independently, agents duplicate work, contradict each other, and act on inconsistent information. One fix is a shared, governed context layer that authorized agents can read from and write to based on their role.Shared context lets agents trade knowledge, skip redundant work, and coordinate off a common source of truth. The same security and governance controls that apply to a single pipeline still apply here. Shared memory without shared governance just spreads inconsistency faster.On AWS, Bedrock AgentCore Memory can persist context across agent interactions, while AgentCore Gateway exposes enterprise tools and APIs to agents through controlled interfaces, keeping memory and tool access separate.Things got trickier once we tested multiple agents on the same workflow. In a batch of 25 concurrent-agent test runs, 3 produced exactly this mismatch: a shipment-tracking agent picked up an updated delivery estimate while a customer-communications agent was still holding the old one in memory. Left to act independently, the two disagreed: the internal dashboard showed one arrival time while the customer got told another.A shared context layer helps, but letting agents freely read and write shared memory isn't enough on its own. Each record needs its source, timestamp, version, and owner attached. Agents should pull the current authorized version before acting on anything consequential, and updates need defined rules for resolving conflicts. Once we added that metadata and forced both agents to check the current version before acting, a follow-up batch of 25 runs came back with zero mismatches. Shared memory makes information available; governance is what makes it trustworthy.The Limitations of Context EngineeringContext engineering makes enterprise AI more reliable, but it's not a cure-all, and it's worth being honest about where it struggles. It only works as well as the organizational information behind it: bad source data means bad answers. Retrieval can surface the wrong context. Misconfigured security can either expose sensitive information or block legitimate access. The infrastructure adds real complexity. And weak governance lets outdated or unreliable knowledge slip through no matter how well everything else is built. In our own testing, the biggest single failure mode wasn't the model at all. When we reviewed a sample of flagged answers, roughly 1 in 5 traced back to source documents more than a year old that nobody had flagged for removal.None of that is an argument against doing this work. It's an argument for doing it deliberately, treating quality, security, and governance as first-class concerns rather than afterthoughts.Where to BeginTeams don't need to solve all of this at once. A reasonable sequence: audit current AI workflows to understand their limitations, identify the knowledge sources that matter for credible answers, build retrieval and ranking pipelines around them, layer in security and governance, and measure context quality on an ongoing basis. Follow that path and context engineering stops being an idea and becomes an operating practice.Putting it together on AWSA practical build might lean on S3 or enterprise databases as knowledge sources, Bedrock Knowledge Bases or OpenSearch Service for retrieval, IAM and KMS for access control and encryption, Bedrock Guardrails for generative-AI protections, AgentCore for agent memory and tool access, and CloudWatch and CloudTrail for visibility and auditing. The services will vary by workload. The sequence won't: find trusted knowledge, retrieve it well, secure and govern access to it, and keep evaluating quality.For the logistics assistant specifically: documents and procedures live in S3, retrieval runs through Bedrock Knowledge Bases or OpenSearch Service, and the application enforces user-specific authorization using document metadata and identity controls before anything reaches the model. Bedrock generates responses from that authorized context, while CloudWatch and application-level tracing capture retrieval results and document versions for troubleshooting. In a multi-agent setup, AgentCore Memory supports persistent context across agents, with the application still responsible for enforcing source precedence and access policy.ConclusionThe throughline across this series has been simple: an AI system is only as good as the context it receives. Part 1 covered what good context looks like, Part 2 covered how to build the pipeline that produces it, and this piece has been about trusting that pipeline once it's live: managing context as a product, securing it, observing it, governing it, and sharing it safely across agents.The next challenge for most organizations isn't writing better prompts. It's becoming context architects: auditing existing workflows, assessing context quality, and building secure, governed pipelines on the cloud. The teams that treat context as a first-class enterprise asset are the ones whose AI stays accurate and useful as it scales.
Read Complete Original Article
Published originally on HackerNoon
Related News
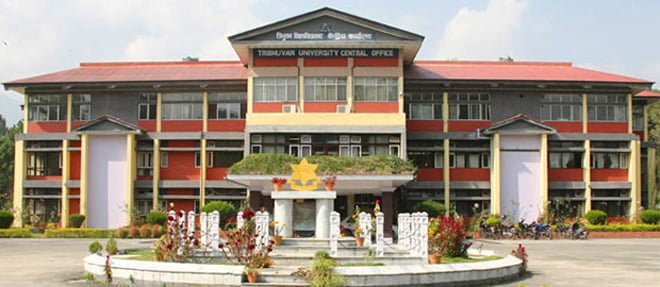
‘डिजिटल त्रिवि’देखि ‘रिसर्च युनिभर्सिटी’सम्मः के–के हुँदैछन् नयाँ काम?
त्रिभुवन विश्वविद्यालयले आफ्नो प्रशासनिक, शैक्षिक तथा प्राज्ञिक संरचनालाई समयानुकूल बनाउँदै डिजिटल सेवा विस्तार, अनुसन्धान प्रवर्द्धन, संस्थागत पुनःसंरचना र वित्तीय सुधारका नयाँ योजना अघि सारेको छ। त्रिविका सहकुलपति एवं शिक्षा तथा खेलकुदमन्त्री सस्मित पोखरेलको अध्यक्षतामा बसेको विश्वविद्यालय सभामा चालु आर्थिक वर्षको नीति तथा कार्यक्रम प्रस्तुत गरिएको थियो। यी योजना कार्यान्वयन भएमा विश्वविद्यालयको प्रशासनिक, शैक्षिक र प्राज्ञिक स्वरूपमा ठूलो फेरबदल आउने अपेक्षा गरिएको ...

इन्टरनेट प्याकेज र शुल्कमा प्राधिकरणको निगरानी, १४ सेवा प्रदायक कारबाहीमा
काठमाडौं । नेपाल दूरसञ्चार प्राधिकरणले स्वीकृत मापदण्ड र निर्देशनविपरीत इन्टरनेट सेवा सञ्चालन गरेको भन्दै १४ वटा इन्टरनेट सेवा प्रदायक कम्पनीलाई जनही ५० हजार रुपैयाँ जरिवाना गरेको छ ।प्राधिकरणले मंगलबार जारी गरेको प्रेस विज्ञप्तिअनुसार अनुमतिपत्रका सर्त उल्लङ्घन गरेको निरीक्षण तथा जाँचबुझबाट पुष्टि भएपछि दूरसञ्चार ऐन, २०५३ को दफा ४७ (१) बमोजिम कारबाही गरिएको हो ।प्राधिकरणका प्रवक्ता मिनप्रसाद अर्यालका अनुसार स्वीकृत प्याकेजअनुसार ...
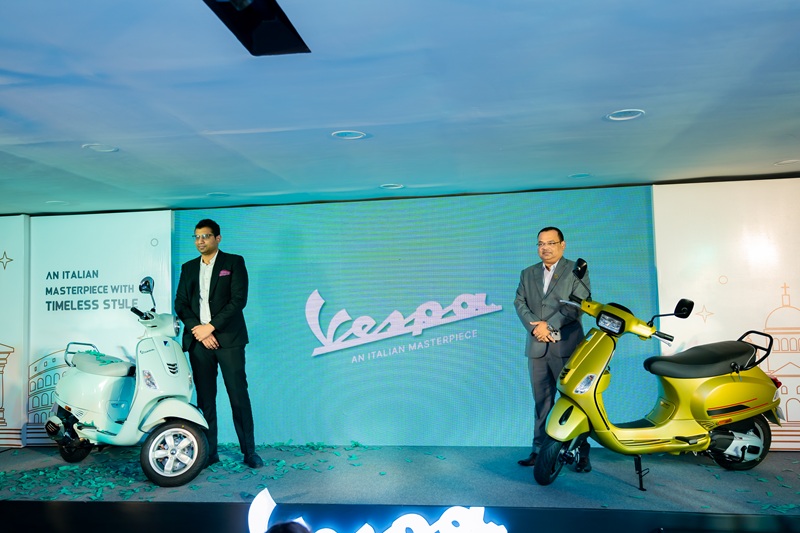
नेपालमा सार्वजनिक भयो भेस्पा १५० एफआई ओबीडी २ स्टेज बी: विशेषता तथा विवरण
२७ असोज, काठमाडौं। इटालियन स्कुटर ब्रान्ड भेस्पाले नेपाली बजारमा नयाँ १५० सिसी क्षमताको स्कुटर सार्वजनिक गरेको छ । नेपालका लागि भेस्पाको आधिकारिक वितरक डेल्टा अटोकर्प प्रालिले भेस्पा १५० एफआई ओबीडी २ स्टेज बी (Vespa 150 FI OBD 2 Stage B) सार्वजनिक गरेको हो । काठमाडौँको त्रिपुरेश्वरस्थित डेल्टा अटोकर्पको शोरुममा आयोजित विशेष कार्यक्रममार्फत नयाँ मोडल सार्वजनिक गरिएको […] The post नेपालमा सार्वजनिक ...
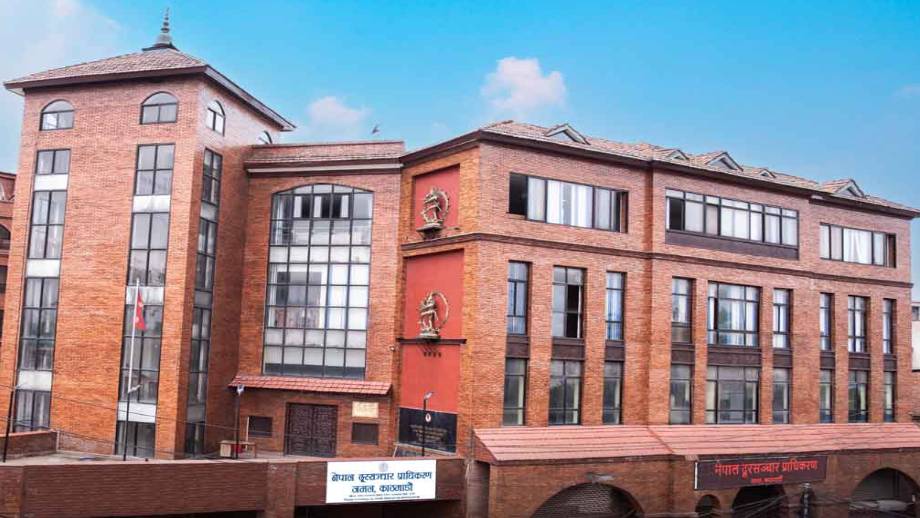
आफूखुशी शुल्क बढाउने १४ इन्टरनेट सेवा प्रदायकलाई प्राधिकरणले तिरायो जरिवाना, स्वीकृति नलिई लागू गरिएका प्याकेज र शुल्क तत्काल बन्द गर्न निर्देशन
नेपाल दूरसञ्चार प्राधिकरणले अनुमतिपत्रका शर्तविपरीत काम गरेको भन्दै १४ वटा इन्टरनेट सेवा प्रदायकलाई जनही ५० हजार रुपैयाँ जरिवाना गरेको छ। प्राधिकरणले आज एक विज्ञप्ति जारी गर्दै इन्टरनेट (इमेलसहित) सेवा सञ्चालन गर्न अनुमति पाएका सेवा प्रदायकले अनुमतिपत्रका सर्त तथा प्रचलित कानुनअनुसार सेवा सञ्चालन नगरेको निरीक्षण तथा जाँचबुझ प्रतिवेदनका आधारमा जरिवाना गर्ने निर्णय गरिएको जनाएको छ। दूरसञ्चार ऐन, २०५३ को दफा ४७(१) बमोजिम ती ...
All Information In One Place
Real-time headlines from trusted sources. Get the app now — stay updated, inspired, and ahead with breaking news!