Bloom Filters in Claims Processing: False Positives, Memory Trade-Offs, and Safe Lookups

A Bloom filter can be wrong in only one direction and that asymmetry can let a claims system skip expensive duplicate and fraud lookups for the honest majority
Key Takeaways
- Bloom Filters in Claims Processing: False Positives, Memory Trade-Offs, and Safe Lookups.
- Most claims are legitimate and new, so in a design like this the check would usually come back “no.” Proving “no” can be expensive.
- It can mean querying very large datasets, sometimes through an external shared service that adds cost and latency.
A Bloom filter can be wrong in only one direction — which is exactly what can let a claims system skip an expensive lookup for the honest majority.Consider the most thankless check a claims system runs: deciding, for every new claim, whether it has been seen before. At first notice of loss, an insurer wants to know whether this VIN, this claimant, this device, or this exact document has already appeared — in its own claims history, in a cross-industry fraud and duplicate database, or on a watch list. Most claims are legitimate and new, so in a design like this the check would usually come back “no.” Proving “no” can be expensive. It can mean querying very large datasets, sometimes through an external shared service that adds cost and latency. Multiply that by every incoming claim, and a pipeline can spend real time and money confirming, over and over, that nothing is wrong.The obvious fix — keep a full in-memory index of everything ever seen — is too large to hold for hundreds of millions of records. The clever fix is to ask a smaller question. We rarely need certainty that a claim is a duplicate or is on a list — the full lookup will confirm that anyway. What we need is a cheap, reliable way to know when a claim is definitely not on the list, so we can skip the lookup entirely. That asymmetry is the whole idea behind the Bloom filter.On a recent data migration involving millions of customer records, I needed a reliable way to catch duplicate claims. I proposed this approach, and it is now being implemented.A probabilistic set in a handful of bitsA Bloom filter is a fixed array of bits, all starting at zero, plus a few independent hash functions. To add a key — a VIN, a claimant ID, a document fingerprint — you hash it with each function to get several positions in the array and set those bits to one. To test a key, you hash it the same way and look at those positions. If any of them is still zero, the key was certainly never added. If all of them are one, the key is probably present. That is the entire mechanism: a few bit-sets on insert, a few bit-reads on query, and no stored keys at all.Because it stores bits rather than keys, the structure is astonishingly compact — on the order of ten bits per element for a one-percent error rate, whether the key is a short VIN or a long document hash. A filter covering a million keys fits in a little over a megabyte and answers every membership test from memory.Wrong in only one directionThe magic isn’t that the filter is small; it is where it is allowed to be wrong. All-ones can happen by coincidence — other keys may have set those same positions — so the filter occasionally says “probably present” for a key it never saw. That is a false positive. But a false negative is impossible: if a key was added, its bits were set, and they are never cleared, so the filter can never claim a key it holds is absent.For a claims pipeline, that one-sided error is exactly the right shape. A false positive is harmless: you run the full duplicate-or-fraud check you would have run anyway, and it comes back clean. A false negative would be the dangerous case — waving through a real duplicate or a flagged claimant — and the Bloom filter structurally never does that. You can trust the “no.” Skipping the expensive lookup is safe precisely because the only mistake the filter can make is to occasionally send you to do more work, never less.The knobs, and what you buy with themThree quantities set the behavior: the number of bits, the number of hash functions, and the number of keys. Add more keys to the same array and more bits flip to one, so false positives rise; spend more bits per key and they fall. The trade is direct and tunable — you buy a lower false-positive rate with memory, not with more lookups. One consequence surprises people: a standard Bloom filter cannot delete. Clearing a key’s bits might clear a bit another key relies on, reintroducing the one error it must never make. If a claimant must come off a set, a counting Bloom filter uses small counters instead of single bits, or you simply rebuild the filter when the reference data is refreshed — which suits a watch list that is regenerated on a schedule.Where it fits claims intakePut a Bloom filter of “keys already seen or on the watch list” in memory beside the intake service — VINs, claimant identifiers, device and telematics IDs, document fingerprints. On every first notice of loss, test the filter first. “Definitely not” — the expected common case for honest, novel claims — skips the expensive cross-database and historical query and lets the claim fast-track into the pipeline. “Maybe” — the rare case — escalates to the full duplicate and fraud investigation. If most claims are new, most of them would clear intake without the costly lookup, and the filter is cheap to rebuild whenever the reference sets change.The same trick, everywhereOnce you see the pattern — a cheap, trustworthy “no” that lets you avoid an expensive lookup — it can show up in many places across a carrier’s systems. Document and photo pipelines can ask “have we already ingested this exact file?” before deduplicating. A cache can avoid storing rarely-read policy documents by only keeping an object the second time it is requested. Notification systems can skip re-sending a message they’ve probably already sent. In each case, the structure answers a common, cheap “no” instantly and defers only the rare “maybe” to the real, expensive check. (The same idea is what lets datastores like Cassandra and RocksDB skip disk reads for records that don’t exist — the idea started in storage engines.)The lessonA Bloom filter is a small idea with a sharp edge: give up exactness, but only about the answer you can afford to be wrong about. When “not on the list” is the common case and a mistaken “maybe” costs only the check you were going to run anyway, a probabilistic filter beats an exact index on both memory and speed. The next time an intake pipeline spends time and money confirming that a claim is clean, ask whether one byte of bits could have answered first.
Read Complete Original Article
Published originally on HackerNoon
Related News
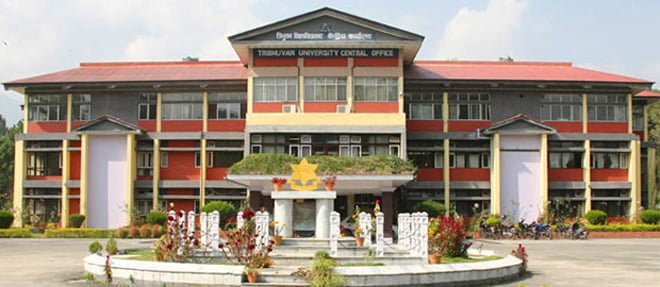
‘डिजिटल त्रिवि’देखि ‘रिसर्च युनिभर्सिटी’सम्मः के–के हुँदैछन् नयाँ काम?
त्रिभुवन विश्वविद्यालयले आफ्नो प्रशासनिक, शैक्षिक तथा प्राज्ञिक संरचनालाई समयानुकूल बनाउँदै डिजिटल सेवा विस्तार, अनुसन्धान प्रवर्द्धन, संस्थागत पुनःसंरचना र वित्तीय सुधारका नयाँ योजना अघि सारेको छ। त्रिविका सहकुलपति एवं शिक्षा तथा खेलकुदमन्त्री सस्मित पोखरेलको अध्यक्षतामा बसेको विश्वविद्यालय सभामा चालु आर्थिक वर्षको नीति तथा कार्यक्रम प्रस्तुत गरिएको थियो। यी योजना कार्यान्वयन भएमा विश्वविद्यालयको प्रशासनिक, शैक्षिक र प्राज्ञिक स्वरूपमा ठूलो फेरबदल आउने अपेक्षा गरिएको ...

इन्टरनेट प्याकेज र शुल्कमा प्राधिकरणको निगरानी, १४ सेवा प्रदायक कारबाहीमा
काठमाडौं । नेपाल दूरसञ्चार प्राधिकरणले स्वीकृत मापदण्ड र निर्देशनविपरीत इन्टरनेट सेवा सञ्चालन गरेको भन्दै १४ वटा इन्टरनेट सेवा प्रदायक कम्पनीलाई जनही ५० हजार रुपैयाँ जरिवाना गरेको छ ।प्राधिकरणले मंगलबार जारी गरेको प्रेस विज्ञप्तिअनुसार अनुमतिपत्रका सर्त उल्लङ्घन गरेको निरीक्षण तथा जाँचबुझबाट पुष्टि भएपछि दूरसञ्चार ऐन, २०५३ को दफा ४७ (१) बमोजिम कारबाही गरिएको हो ।प्राधिकरणका प्रवक्ता मिनप्रसाद अर्यालका अनुसार स्वीकृत प्याकेजअनुसार ...
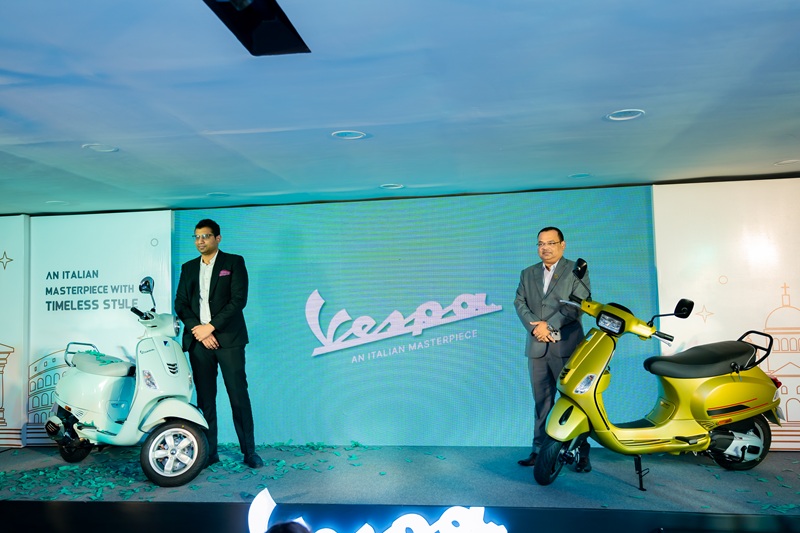
नेपालमा सार्वजनिक भयो भेस्पा १५० एफआई ओबीडी २ स्टेज बी: विशेषता तथा विवरण
२७ असोज, काठमाडौं। इटालियन स्कुटर ब्रान्ड भेस्पाले नेपाली बजारमा नयाँ १५० सिसी क्षमताको स्कुटर सार्वजनिक गरेको छ । नेपालका लागि भेस्पाको आधिकारिक वितरक डेल्टा अटोकर्प प्रालिले भेस्पा १५० एफआई ओबीडी २ स्टेज बी (Vespa 150 FI OBD 2 Stage B) सार्वजनिक गरेको हो । काठमाडौँको त्रिपुरेश्वरस्थित डेल्टा अटोकर्पको शोरुममा आयोजित विशेष कार्यक्रममार्फत नयाँ मोडल सार्वजनिक गरिएको […] The post नेपालमा सार्वजनिक ...
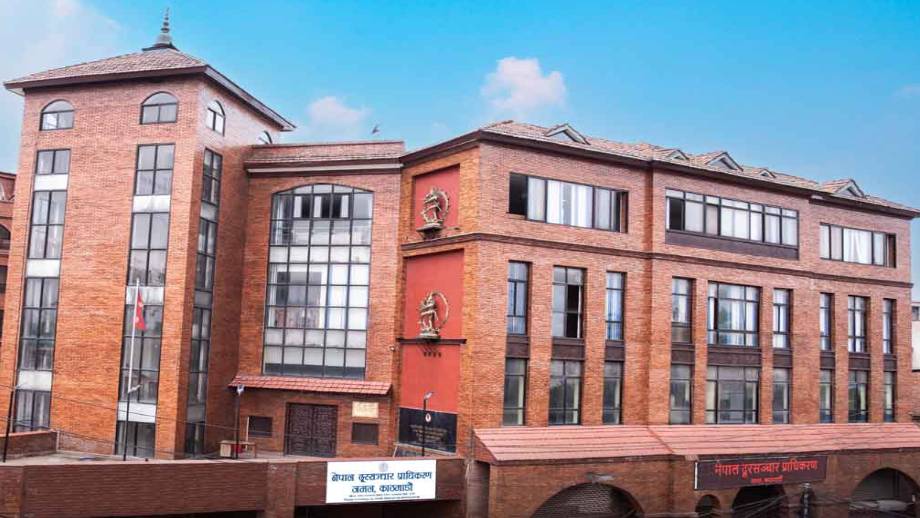
आफूखुशी शुल्क बढाउने १४ इन्टरनेट सेवा प्रदायकलाई प्राधिकरणले तिरायो जरिवाना, स्वीकृति नलिई लागू गरिएका प्याकेज र शुल्क तत्काल बन्द गर्न निर्देशन
नेपाल दूरसञ्चार प्राधिकरणले अनुमतिपत्रका शर्तविपरीत काम गरेको भन्दै १४ वटा इन्टरनेट सेवा प्रदायकलाई जनही ५० हजार रुपैयाँ जरिवाना गरेको छ। प्राधिकरणले आज एक विज्ञप्ति जारी गर्दै इन्टरनेट (इमेलसहित) सेवा सञ्चालन गर्न अनुमति पाएका सेवा प्रदायकले अनुमतिपत्रका सर्त तथा प्रचलित कानुनअनुसार सेवा सञ्चालन नगरेको निरीक्षण तथा जाँचबुझ प्रतिवेदनका आधारमा जरिवाना गर्ने निर्णय गरिएको जनाएको छ। दूरसञ्चार ऐन, २०५३ को दफा ४७(१) बमोजिम ती ...
All Information In One Place
Real-time headlines from trusted sources. Get the app now — stay updated, inspired, and ahead with breaking news!